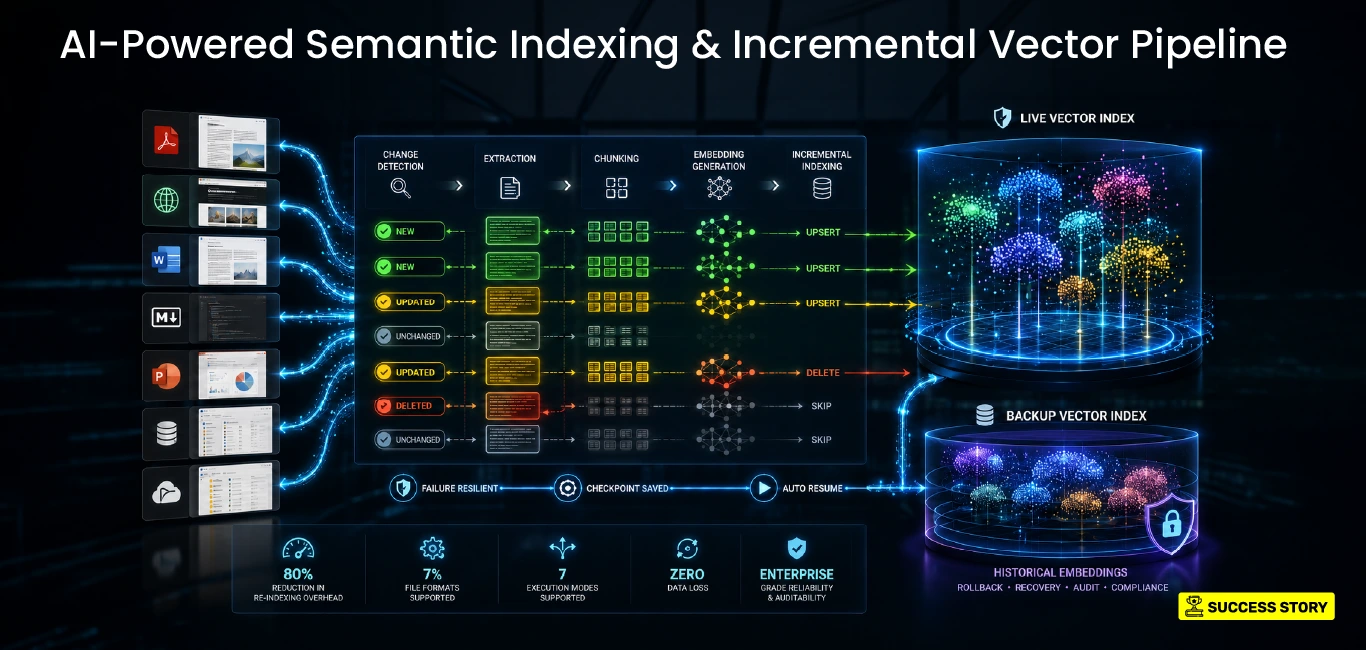
Success Story: AI-Powered Semantic Indexing & Incremental Vector Pipeline
About the Client
The client operates in the Artificial Intelligence and Enterprise Software sector, focusing on intelligent knowledge management, semantic search, and AI-powered document retrieval solutions. Their platform serves organizations that require fast, accurate, and continuously up-to-date access to large volumes of unstructured content through AI-powered semantic indexing, including documentation portals, regulatory repositories, internal knowledge bases, and multi-format document archives. The client needed a backend pipeline powerful enough to keep pace with constantly evolving content across multiple sources without compromising performance or reliability.
Client Requirements
The client’s goal was to build a scalable, failure-tolerant semantic indexing system capable of continuously tracking and re-indexing evolving content from multiple sources. Specifically, the solution needed to:
- Eliminate costly full re-indexing cycles by detecting only new, updated, or deleted content on each run.
- Process seven file formats — PDF, HTML, DOC, DOCX, Markdown, PPT, PPTX — from a single unified pipeline.
- Track URL-level status across domain crawls, list-based sources, and local folder ingestion with persistent state.
- Handle transient embedding and vector store failures gracefully — without data loss or duplicate processing.
- Back up old embeddings for updated or deleted URLs to support rollback, audit trails, and compliance requirements.
- Provide flexible execution modes so teams can trigger targeted, scheduled, or full ingestion without code changes.
- Maintain a clean, auditable state model with per-URL extraction, chunking status, chunk IDs, and timestamps.
Project Details
Service
Custom Software Development –
AI / Semantic Search Pipeline
Technologies & Tools
Spring Boot (Java), Pinecone Vector Database, OpenAI Embeddings API
Vector Database Pinecone
Live Index (active embeddings) + Backup Index (historical embeddings for updated/deleted URLs)
Challenges
The project presented a series of complex engineering and architectural challenges spanning performance, reliability, data integrity, and multi-format processing:

Incremental Change Detection at Scale
Content repositories contained thousands of URLs updated on varying schedules. Full re-indexing on every cycle was computationally prohibitive. A robust, lightweight JSON state architecture was needed to detect changes, survive partial failures, and avoid duplicate indexing across restarts.

Heterogeneous File Format Processing
Source content spanned PDFs, HTML pages, Word documents (DOC and DOCX), Markdown files, and PowerPoint presentations (PPT and PPTX). Each format required a dedicated extraction processor with consistent output normalization, presenting significant routing and engineering complexity.

Controlled Pipeline Exit
Embedding generation and Pinecone vector store operations are prone to transient failures during large-scale ingestion. Without a controlled failure policy, a single failed URL could silently corrupt the indexing state or cause the pipeline to hang indefinitely.

Embedding Safety for Updated & Deleted Content
When URLs were updated or removed, their existing Pinecone embeddings were deleted from the live index. Without a safety net, this created a risk of irreversible data loss — particularly critical in regulated or compliance-sensitive environments.
Solutions
To address the client’s challenges, we designed and delivered a modular, AI-powered semantic indexing pipeline built for enterprise scale and operational reliability.
Stateful Change Detection
Implemented a JSON-based tracking system that monitors every content source and identifies only what is new, updated, or deleted — eliminating redundant re-processing entirely.
Multi-Format AI Processing
Built dedicated processors for each of the seven supported file formats, ensuring consistent, high-quality content extraction regardless of document type or source.

Failure-Resilient Pipeline
Introduced a controlled failure policy that safely halts the pipeline at any point of disruption, preserves all progress, and allows seamless resumption — with zero data loss.
Historical Embedding Preservation
Deployed a dedicated backup index that automatically retains previous versions of all updated or deleted content, enabling rollback, compliance audits, and data recovery on demand.
Flexible Execution Modes
Delivered seven configurable ingestion modes giving teams full control over indexing scope — from targeted single-source updates to full pipeline runs — without any code changes.
Results
The semantic indexing pipeline delivered measurable, enterprise-grade outcomes across all six proof dimensions:
| Impact Area | Metric | Outcome |
| Business Challenge | Re-indexing Efficiency | 80% reduction in re-indexing overhead — only new and updated content is re-processed, eliminating redundant embedding generation |
| Delivery Scale | Format & Mode Coverage | 7 file formats and 7 execution modes supported from a single unified pipeline — domain crawl, list-based, and folder ingestion all covered |
| Measurable Outcome | Operational Reliability | Zero data loss on failure — atomic JSON state persistence and consecutive failure policy allow safe pipeline resumption every time |
| Timeline Reduction | Deployment Speed | CLI-driven Spring Boot app with no re-setup required — pipeline resumes from exact failure point, eliminating rework and manual intervention |
| Productivity Gains | Ingestion Flexibility | 6 targeted execution modes give teams full control over indexing scope and scheduling without any code changes |
| Complexity Solved | Data Integrity & Compliance | Dedicated Pinecone backup index preserves all historical embeddings — enabling rollback, audit trails, and compliance-safe retention on demand |
Contact Us for Scalable Semantic Indexing Solutions
Looking to eliminate inefficiencies in your AI data pipeline? Connect with us at sales@fidelsoft.com and let’s turn your content into searchable, actionable intelligence.